
Documents to decisions
Make documents usable — not merely searchable.
Extract the fields your workflow actually needs, preserve links to original evidence, and make the resulting data available to people, APIs, analytics, and AI assistants.
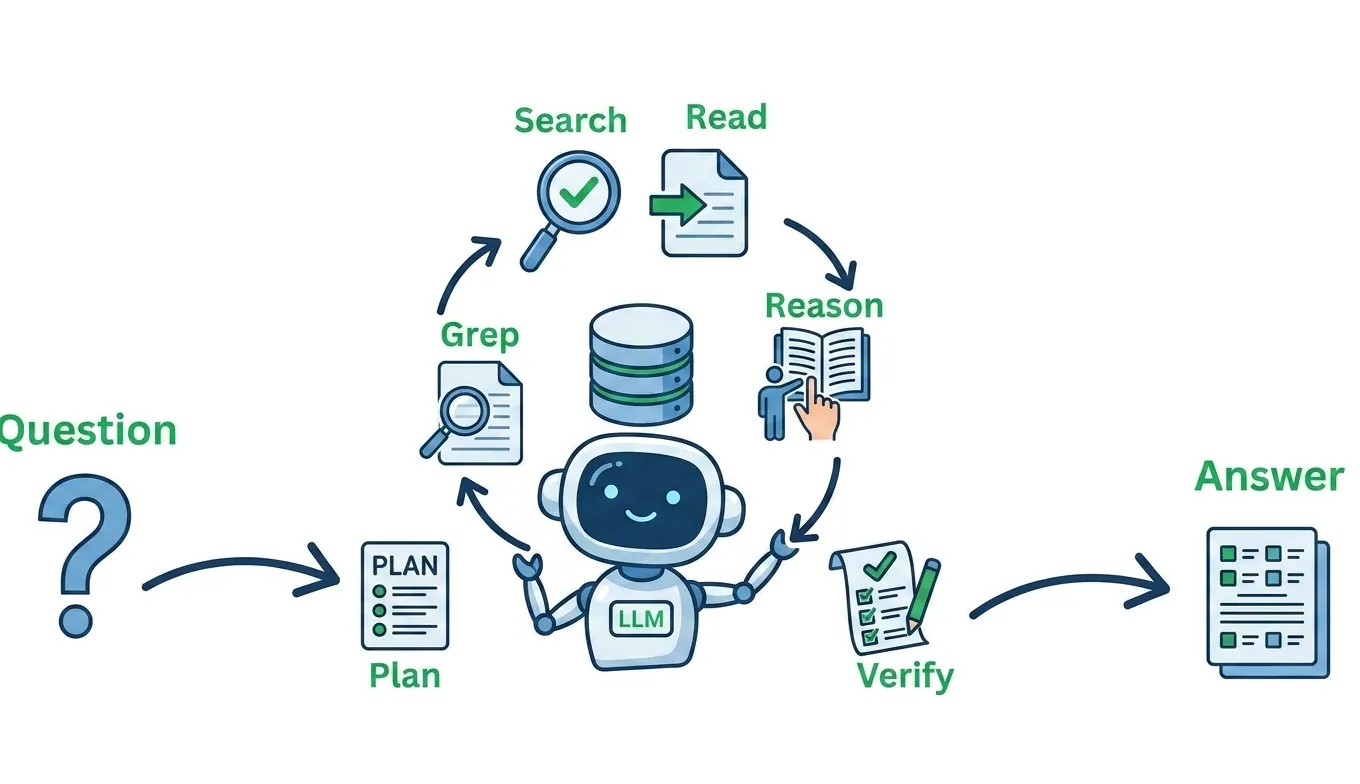
A dependable document pipeline
Schema-aware extraction
Map varied documents into defined business fields rather than returning an unstructured wall of text.
Evidence and traceability
Keep originals, page references, confidence, and review status connected to every extracted value.
Data ready for work
Write validated output to files, databases, APIs, search, or downstream agent workflows.
Delivery path
From representative samples to scaled processing
- 01
Collect document types, schemas, quality rules, and review needs.
- 02
Benchmark extraction against representative and difficult samples.
- 03
Design queues, retries, validation, evidence, and human review.
- 04
Connect storage, search, APIs, reporting, and operational workflows.
FAQ
Questions teams ask
Which file types are supported?
PDFs and images are common starting points. The final set depends on document structure, source systems, and required fidelity.
Can this run in a private environment?
Yes. Data residency, networking, storage, and model deployment are designed around your security requirements.
Contact
What would make Document AI work in your environment?
Share the workflow, data, constraints, and intended outcome. We will propose a next step that can genuinely test the opportunity.